Introduction
AI is reshaping education at a rapid clip, with personalized tutoring and learning analytics promising to overhaul how students learn. Yet regulation has not kept pace with this technological surge, and serious questions have emerged about student data privacy, algorithmic fairness, and the safety of minors. This piece examines the key pillars—privacy-preserving architectures, bias detection, minor safeguarding, and transparency—that are needed to build educational AI that is both innovative and worthy of trust, so that digital classrooms serve every learner fairly.
Privacy-Preserving Architectures for Student Data
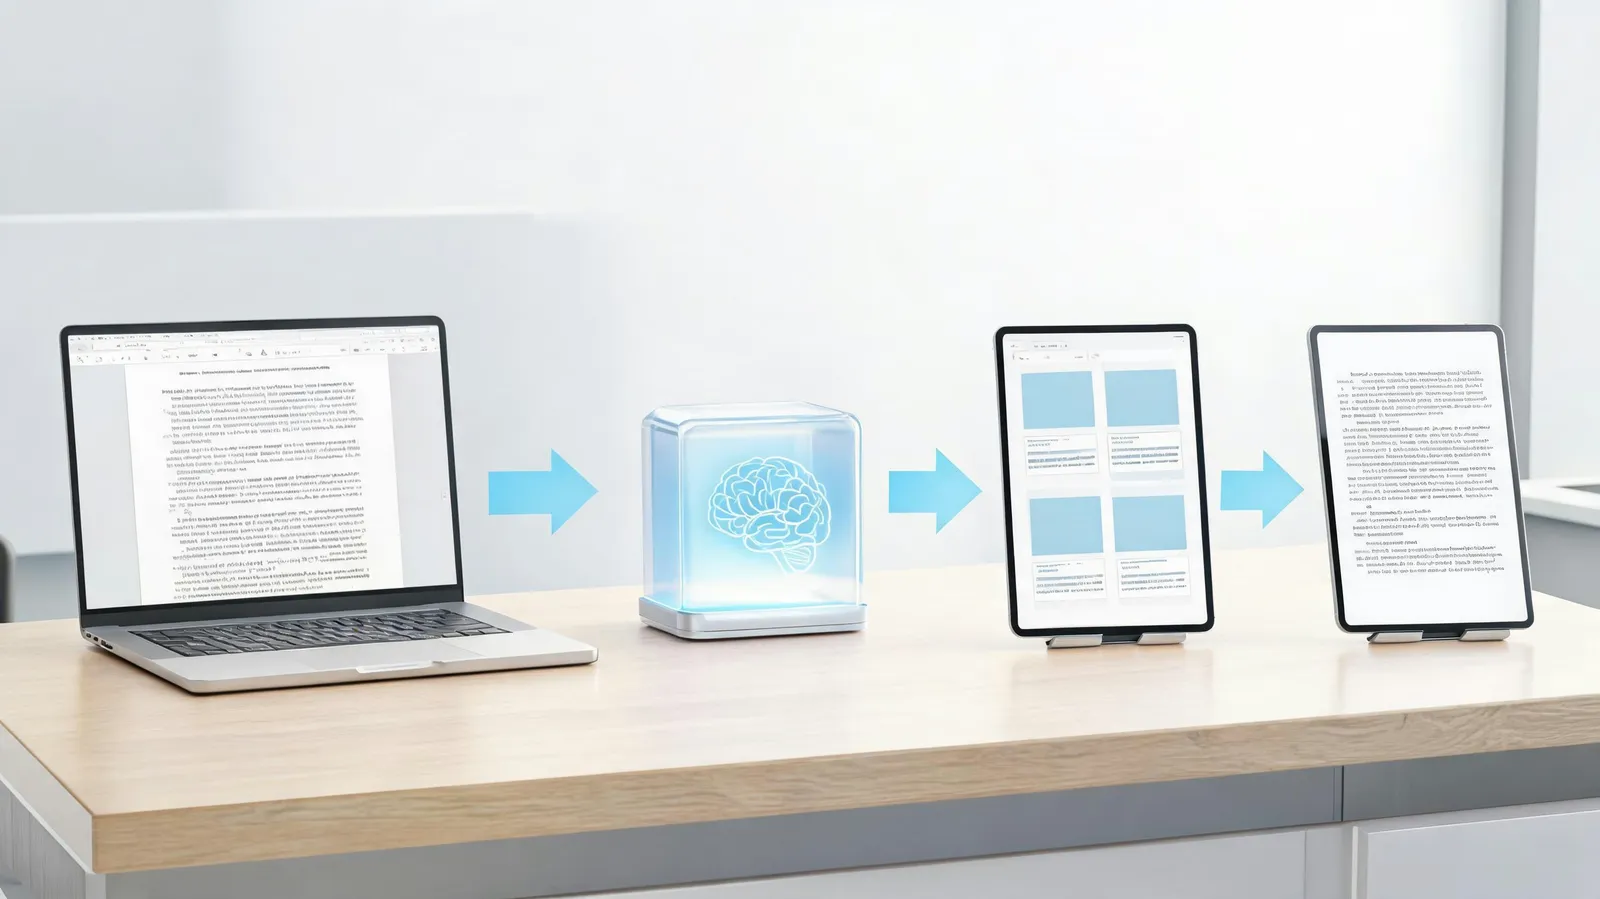
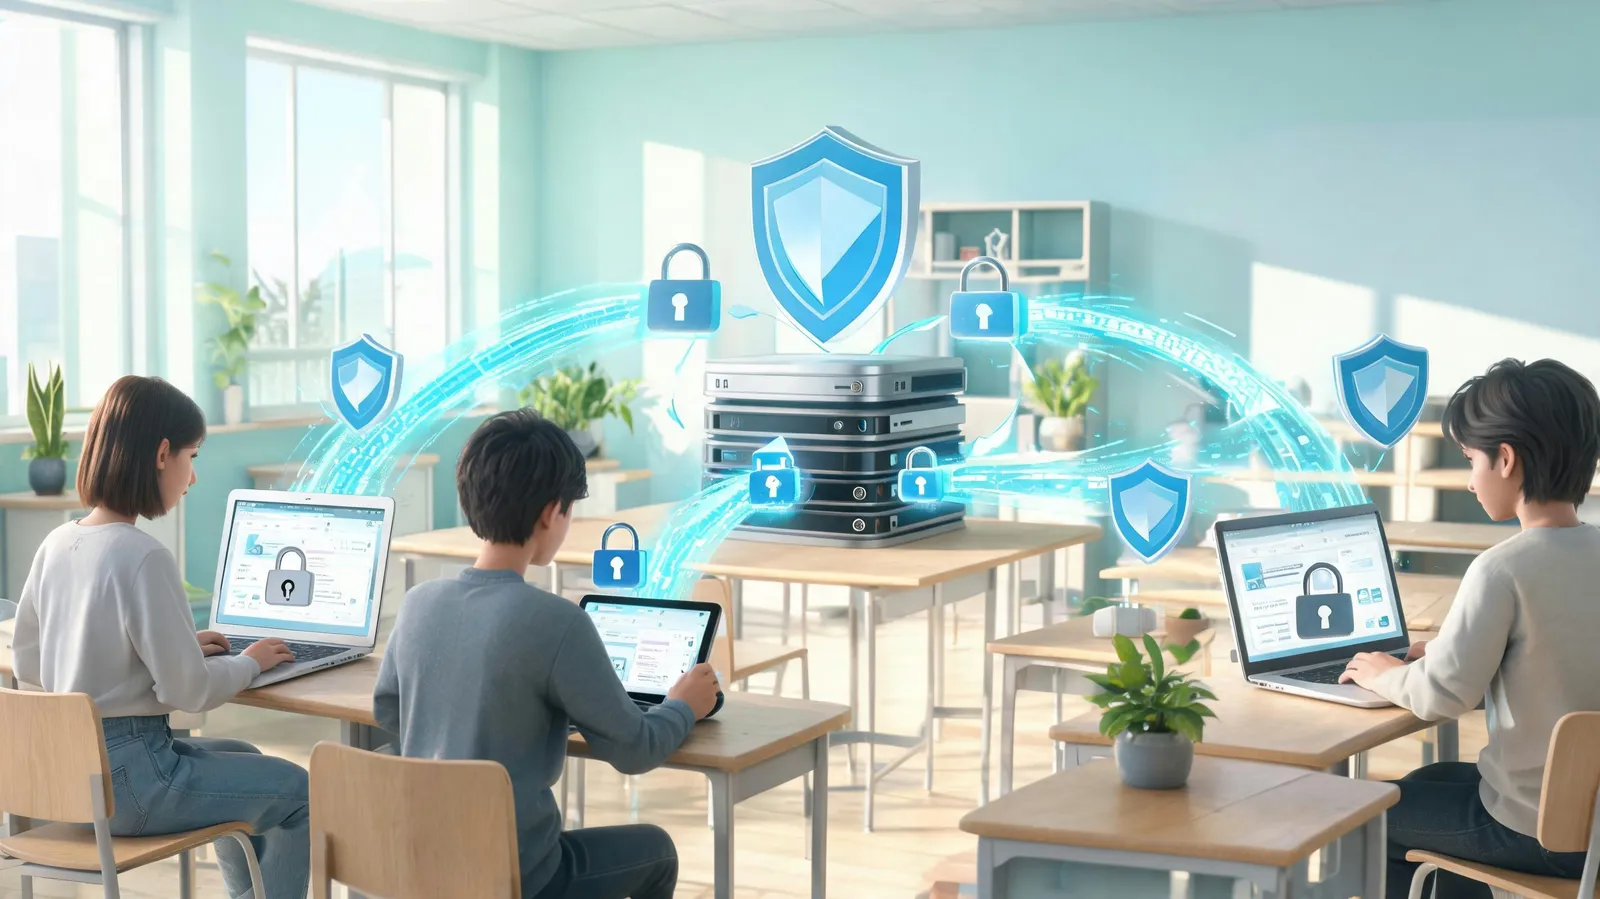
AI systems gather extensive student information, ranging from learning patterns to personal details, which heightens the danger of breaches and misuse. Privacy-preserving architectures are critical for shielding students while still allowing personalized learning. Approaches like federated learning and differential privacy let models learn from data without pooling sensitive information in one place. In federated learning, for instance, AI tutors improve by training on data across many devices while the data stays on the student's device. Differential privacy introduces statistical noise into datasets so that individual students cannot be identified. Data minimization and anonymization further cut risks by limiting collection to what is necessary and removing identifying details. Regulations such as GDPR and FERPA require these protections, and schools that have implemented such strategies have experienced fewer breach risks and stronger trust.
Case studies demonstrate the effectiveness of these approaches. A California school district that adopted a federated learning platform for math tutoring saw a 40% drop in data breach incidents and greater parent satisfaction. Likewise, anonymization techniques in edtech platforms have allowed aggregated data to be shared safely for research without exposing student identities. These examples show that privacy and personalization can coexist when architectures are built with protection in mind.
Bias Detection and Mitigation in Tutoring Content
Algorithmic bias in AI tutoring systems can entrench and even widen educational inequalities. Bias may arise from training data that underrepresents certain groups or from design choices that unintentionally favor majority populations. A reading recommendation algorithm, for example, might suggest books mainly featuring male protagonists, putting female students at a disadvantage. Research indicates that such biases can produce disparate impact, with underrepresented groups receiving less challenging content or fewer opportunities.
Finding and reducing bias calls for proactive steps. Fairness indicators and adversarial testing can expose biased outcomes. Tools such as IBM's AI Fairness 360 offer metrics for assessing disparities across groups. Adversarial testing means deliberately probing the system with edge cases to reveal discriminatory behavior. Once bias is identified, mitigation strategies include rebalancing training data, adjusting model objectives, and applying fairness constraints. Case studies from edtech companies show that routine bias audits and diverse development teams substantially reduce biased recommendations, resulting in more equitable learning experiences.
Safeguarding Minors in Conversational AI Systems
Conversational AI—chatbots and virtual tutors, for example—presents distinct risks to minors, including exposure to inappropriate content, manipulation, and over-reliance. There have been reports of AI chatbots giving harmful advice to children, underscoring the need for strong safeguards. Research on child-AI interaction stresses that minors are more easily influenced and may not grasp AI's limitations.
Design principles for child-safe AI include age-appropriate responses, content filters, and parental controls. AI tutors, for instance, should use simple language, steer clear of sensitive topics, and redirect to human help when necessary. Parental dashboards can let guardians monitor interactions and set boundaries. Organizations such as the Family Online Safety Institute offer guidelines that emphasize transparency and consent. Successful implementations, like the UK's ChildWise AI tutor, have incorporated these principles and shown increased engagement and safety.
Transparency, Consent, and Regulatory Compliance
Transparency and informed consent are the bedrock of trust in educational AI. Stakeholders—parents, teachers, and students—need to understand how AI systems operate and what data they collect. Explainable AI techniques, such as giving clear rationales for recommendations, help make decisions less opaque. Surveys suggest that parents are more inclined to support AI tools when schools communicate openly about data practices.
Compliance with data protection laws like GDPR, COPPA, and emerging AI regulations is essential. COPPA requires verifiable parental consent to collect data from children under 13. GDPR mandates data protection impact assessments and transparency. Cases of compliance failures, such as fines for edtech companies that mishandled student data, highlight the importance of adherence. Conversely, schools that proactively comply and engage stakeholders report higher trust and smoother adoption.
Conclusion
Establishing trust in educational AI demands a multifaceted approach centered on privacy, bias mitigation, minor safeguarding, and transparency. These pillars are not just regulatory hurdles but essential foundations for equitable and effective learning environments. As AI continues to evolve, ongoing collaboration among educators, developers, and policymakers is crucial to adapt to emerging challenges and ensure that technology serves all students fairly. By prioritizing ethics alongside innovation, we can create digital classrooms where trust and learning thrive together.