Trust in what we see, read, and cite online is being worn down by the proliferation of AI-generated content. Three emerging remedies—content provenance specifications such as C2PA, watermarking, and AI-text detection—each hold out the promise of restoring confidence, yet each comes with its own set of limitations. This article looks at how well these approaches work in practice and makes the case that a durable trust ecosystem depends on using them in combination rather than betting on any one of them.
1. Content Credentials and C2PA Adoption Across Publishing and Social Platforms
Provenance standards are built to answer a basic question: where did a piece of media originate, and what changes have been made to it? The Coalition for Content Provenance and Authenticity (C2PA) has become the leading technical specification, attaching cryptographically signed metadata to media at the moment of capture or editing.
1.1 How C2PA Content Credentials Work
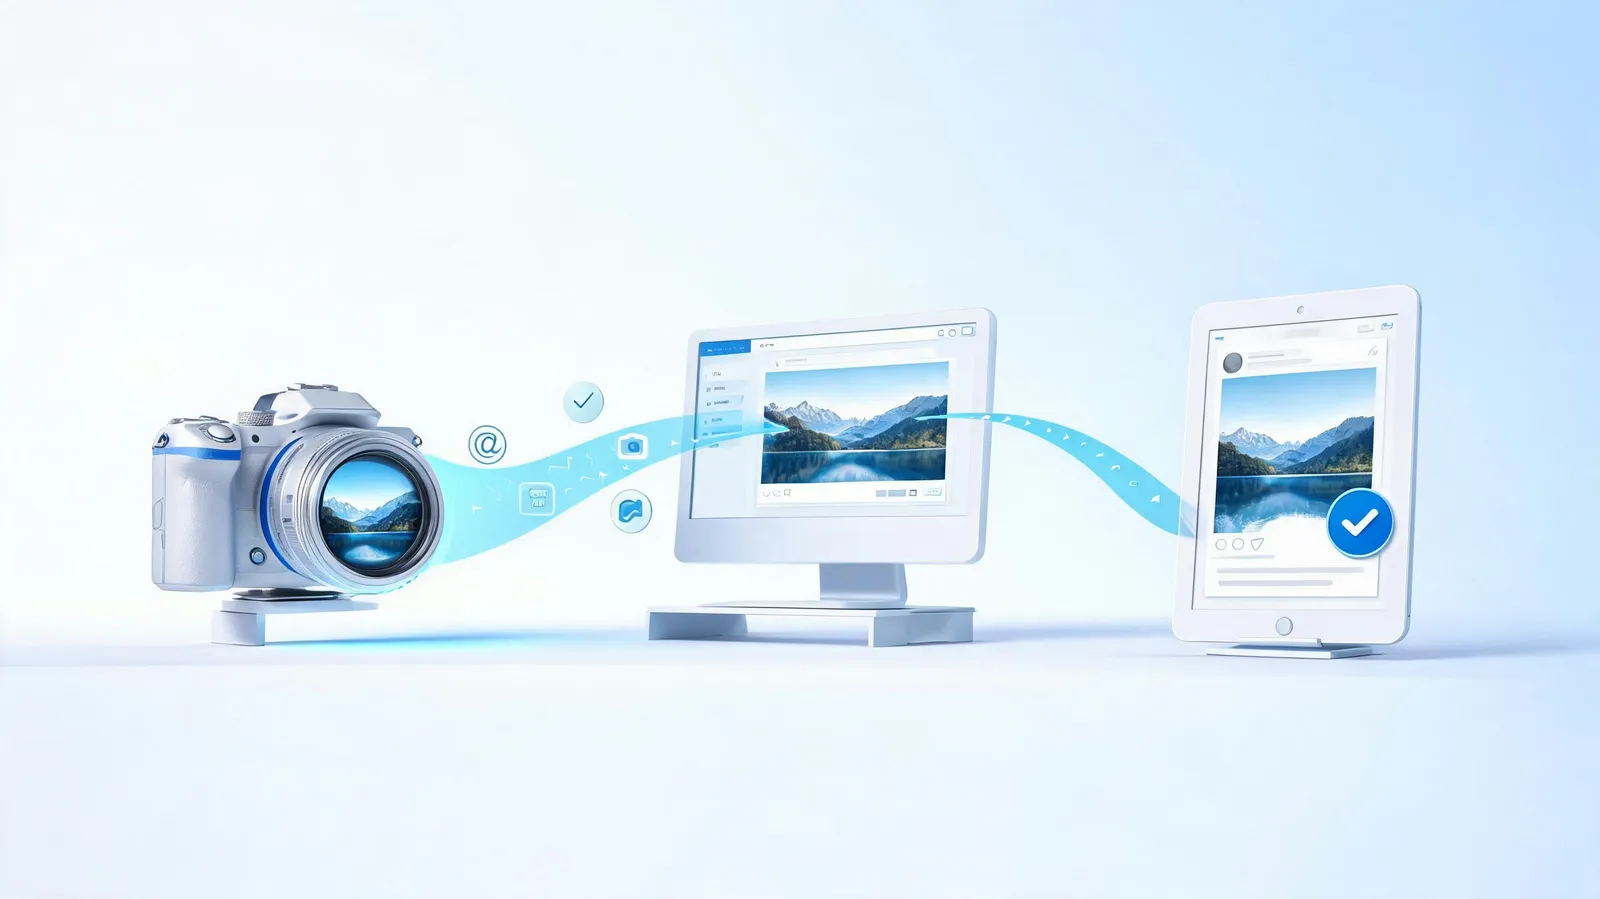
C2PA content credentials operate on a signer/validator model. When a compatible camera captures a photo or compliant software edits it, a manifest is generated that contains assertions about the content's origin, editing history, and creator. This manifest is cryptographically signed, producing a tamper-evident record. Validators—social platforms or verification tools, for example—can then check the signature and, if the provenance chain is intact, display a verification badge.
Early adopters include major camera manufacturers such as Leica and Nikon, publishers including The New York Times and BBC, and platforms like Adobe and Microsoft. These organizations have built C2PA support into their workflows, allowing provenance to be tracked end-to-end from capture to publication.
1.2 Adoption Gaps and Interoperability Challenges
Momentum is growing, but adoption is uneven. A 2023 survey by the Content Authenticity Initiative found that 78% of publishers recognize the importance of provenance, yet only 32% have implemented C2PA at scale. Social platforms pose a particular problem: some display provenance metadata, while others strip it entirely on upload, breaking the chain of trust.
Governance, privacy, and liability concerns also slow adoption. Publishers are wary of exposing proprietary editing workflows, and platforms face uncertain liability if they display credentials that later turn out to be false. Interoperability across different C2PA implementations is still a work in progress, with varying levels of support for different assertion types.
2. Robustness of Watermarking Against Editing, Paraphrasing, and Adversarial Removal
Watermarking embeds a signal directly into content—image, audio, or text—that can later be detected to identify AI generation or ownership. Unlike provenance metadata, which can be stripped away, watermarks are designed to survive transformations.
2.1 Types of Watermarks and Embedding Mechanisms
Image watermarking methods include spatial domain techniques (altering pixel values), frequency domain approaches (modifying DCT or wavelet coefficients), and learned watermarking using neural networks. Audio watermarks often rely on imperceptible frequency shifts or phase modifications. Text watermarking typically works by biasing token sampling during generation—favoring certain words based on a secret key, for instance—so that the resulting text contains a statistically detectable pattern.
Each method strikes a different balance among imperceptibility, capacity, and robustness. Learned watermarking has shown promise for surviving common edits, but no method is universally robust.
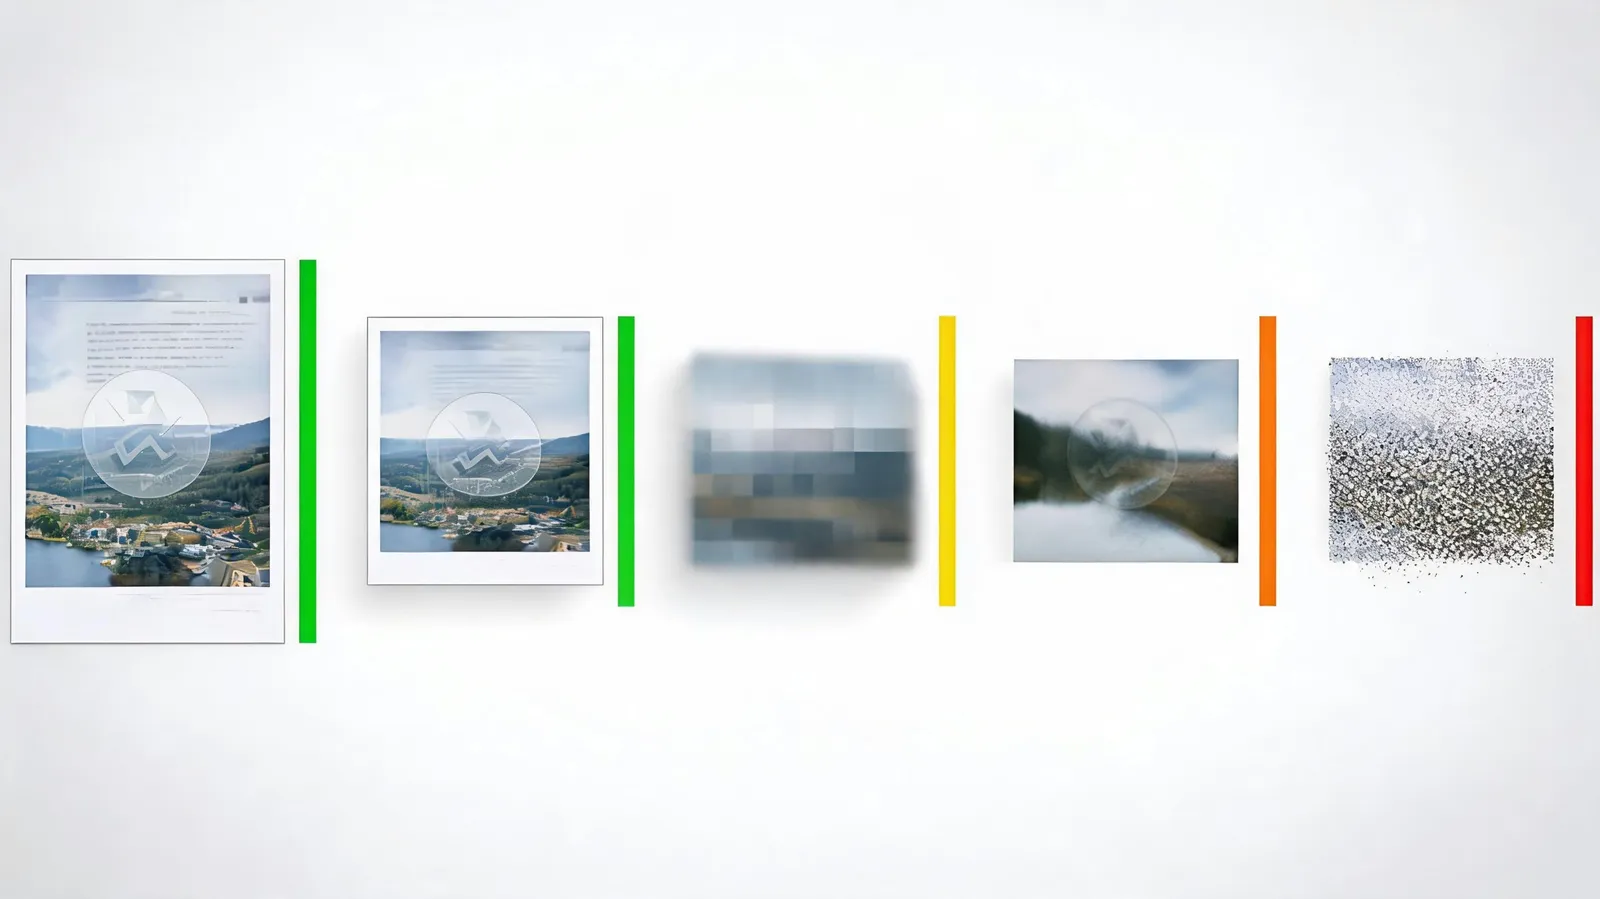
2.2 Attack Surface: Cropping, Compression, Paraphrasing, and Adversarial Removal
Watermarks face a relentless attack surface. Cropping an image can remove spatial watermarks entirely. Lossy compression, common on social media, degrades frequency-domain signals. For text, paraphrasing—rewriting content while preserving meaning—can destroy token-sampling patterns. Adversarial techniques, such as adding carefully crafted noise or using surrogate models to approximate and remove watermarks, have been documented in research literature.
A 2024 study by researchers at ETH Zurich found that even robust image watermarks could be removed with 85% success using a combination of cropping and adversarial perturbation. Text watermarks proved even more fragile: simple paraphrasing tools reduced detection accuracy from 95% to below 40%. These findings underscore that watermarking alone cannot guarantee content authenticity—it is a deterrent, not a solution.
3. Limits of AI-Text Detectors and Risks of False Accusations in Academic and Professional Settings
AI-text detectors analyze patterns in writing to estimate the likelihood of machine generation. They are increasingly used in academia, hiring, and publishing—but their accuracy is fundamentally limited, and the human costs of misclassification are high.
3.1 How AI-Text Detectors Work and Why Accuracy Is Limited
Most detectors rely on heuristics like perplexity (how predictable the text is) and burstiness (variation in sentence length and structure), or on classifier models trained to distinguish human from machine text. However, these methods struggle with adversarial paraphrasing, domain-specific writing, and non-native English writers, whose prose often exhibits lower perplexity and burstiness—leading to false positives.
A 2023 study by Stanford researchers found that AI detectors falsely flagged 61% of essays written by non-native English speakers as AI-generated, compared to just 5% for native speakers. Even for native speakers, false-positive rates ranged from 1% to 15% depending on the detector and text type. These error rates are unacceptable when stakes include academic penalties or job loss.
3.2 Real-World Harms: False Accusations in Academia, Hiring, and Publishing
Documented cases include a Vanderbilt University student wrongly accused of using ChatGPT for an essay, and a freelance writer whose contract was terminated after a detector flagged her work. In hiring, candidates have been rejected based on detector scores without human review. These incidents highlight the need for due process: detectors should be used as screening tools, not as evidence of misconduct. Human review, appeals processes, and transparency about detector limitations are essential safeguards.
4. Combining Provenance, Watermarking, and Detection into a Layered Trust Strategy
No single technology can solve the AI-content trust problem. A defense-in-depth approach combines provenance, watermarking, and detection, each addressing different parts of the challenge.
4.1 Complementary Roles: Provenance for Origin, Watermarking for Persistence, Detection for Screening
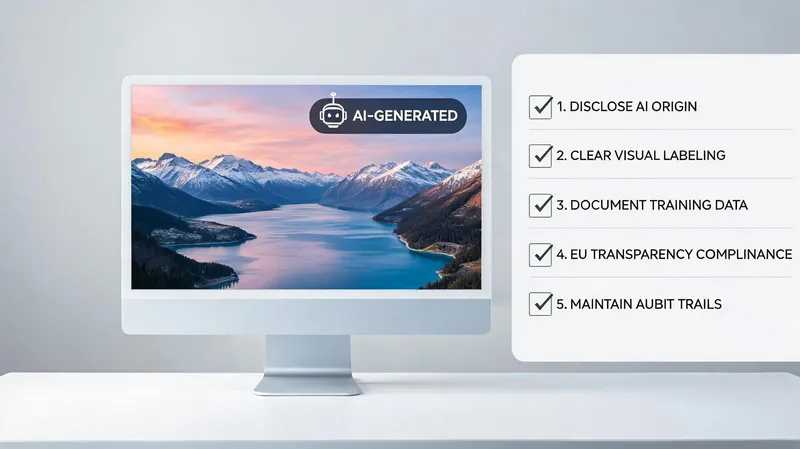
Provenance standards like C2PA provide the strongest guarantee of origin—when metadata is present and intact. Watermarking offers persistence through transformations, acting as a backstop when metadata is stripped. Detection provides a screening mechanism for content lacking either signal, albeit with limited accuracy. Together, they create multiple layers of evidence.
Case examples include the BBC's pilot program combining C2PA credentials with watermarking for user-generated content, and Microsoft's integration of provenance and detection tools in its Designer platform. These layered deployments demonstrate that while each layer has failure modes, the combination is more resilient than any single approach.
4.2 Policy and Process Recommendations for Responsible Adoption
Organizations should adopt human-in-the-loop review for any punitive action based on detection. Appeals processes and transparency about limitations are critical. Standards bodies should continue developing interoperability profiles for C2PA and watermarking, while regulators should focus on protecting individuals from false accusations and ensuring platform transparency.
Conclusion
Provenance standards, watermarking, and detection each address different parts of the AI-content trust problem, but none is sufficient alone. Over-reliance on detectors, in particular, risks harming innocent creators and professionals. The path forward requires interoperable standards, more robust watermarking, and policy frameworks that prioritize human oversight. By deploying these technologies as complementary layers, we can build a trust ecosystem that is resilient, fair, and effective in the age of AI-generated content.