Introduction
Generative models have spread quickly from experimental settings into routine use, churning out text, imagery, and other media at scale. These systems are far from neutral: they can reproduce, and in some cases magnify, biases embedded in their training data, producing representational harms that fall disproportionately on marginalized communities. Grasping where bias comes from, building sound ways to measure it, and putting effective countermeasures in place are all necessary steps toward fair and dependable AI.
1. Demographic Bias in Image and Text Outputs
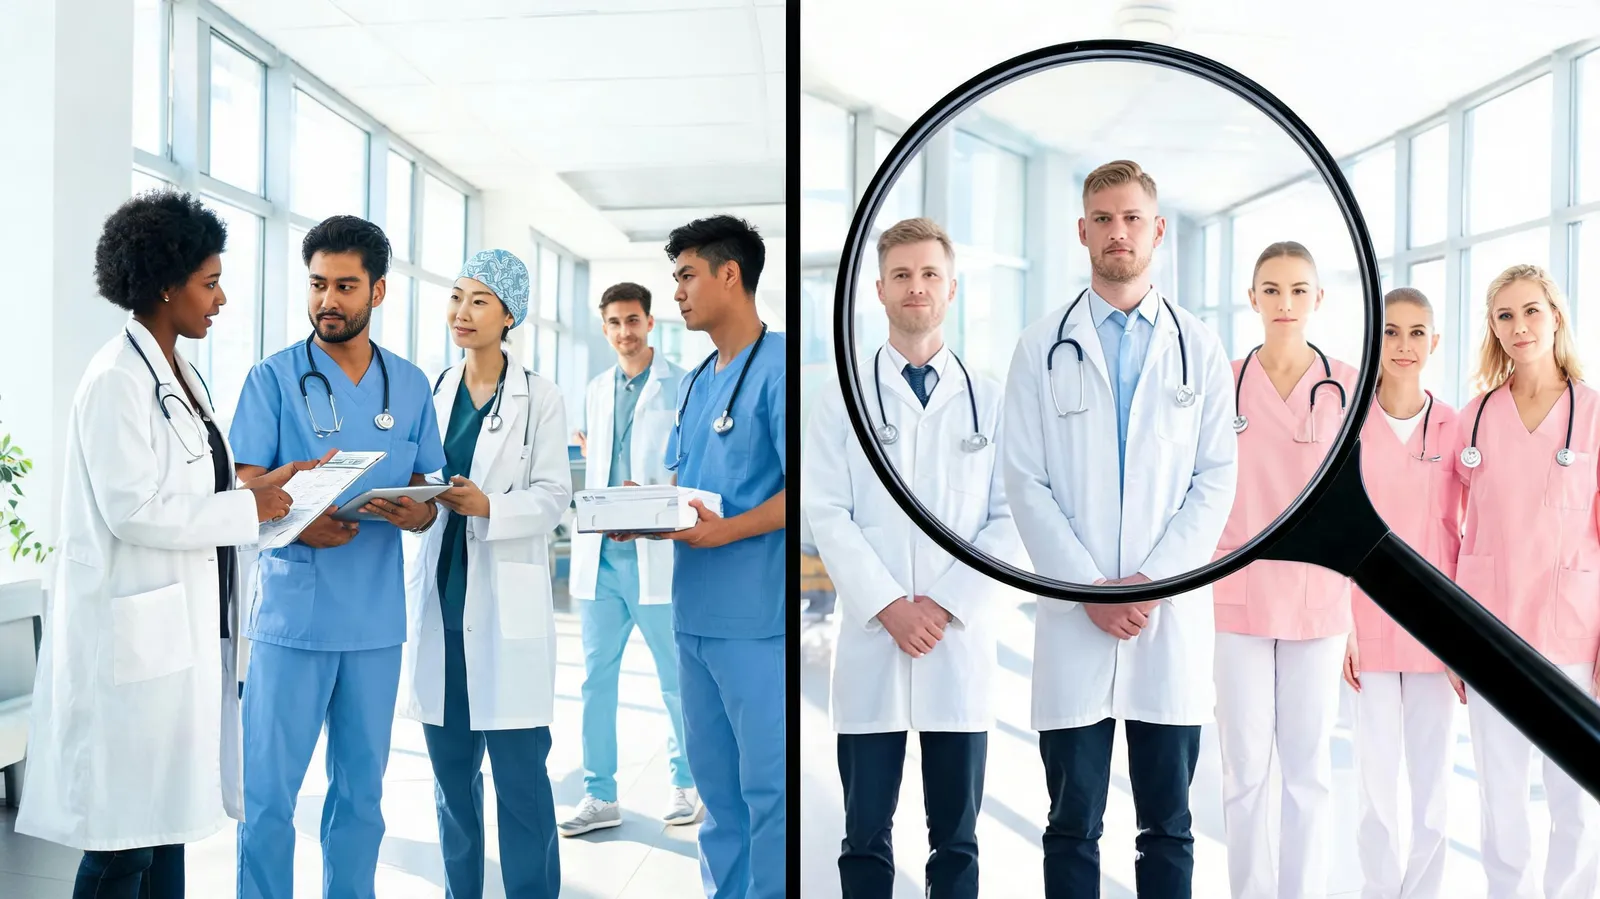
Across both visual and textual modalities, generative models show bias tied to demographic groups. Stereotyping, underrepresentation, and misrepresentation are among the recurring patterns. Image generators, for instance, tend to render doctors as men and nurses as women, and can link particular ethnicities with criminality. Text generators make similar profession-gender associations, pairing "engineer" with men and "secretary" with women.
Several forces drive these outcomes: the training data, the model architecture, and the optimization targets. Datasets that are imbalanced and underrepresent certain groups yield skewed outputs. Language models pretrained on biased corpora reinforce stereotypes through statistical associations. Optimization objectives, even when intended to be benign, can unintentionally entrench bias when they are not designed with care.
2. Assessing Factuality, Toxicity, and Stereotyping
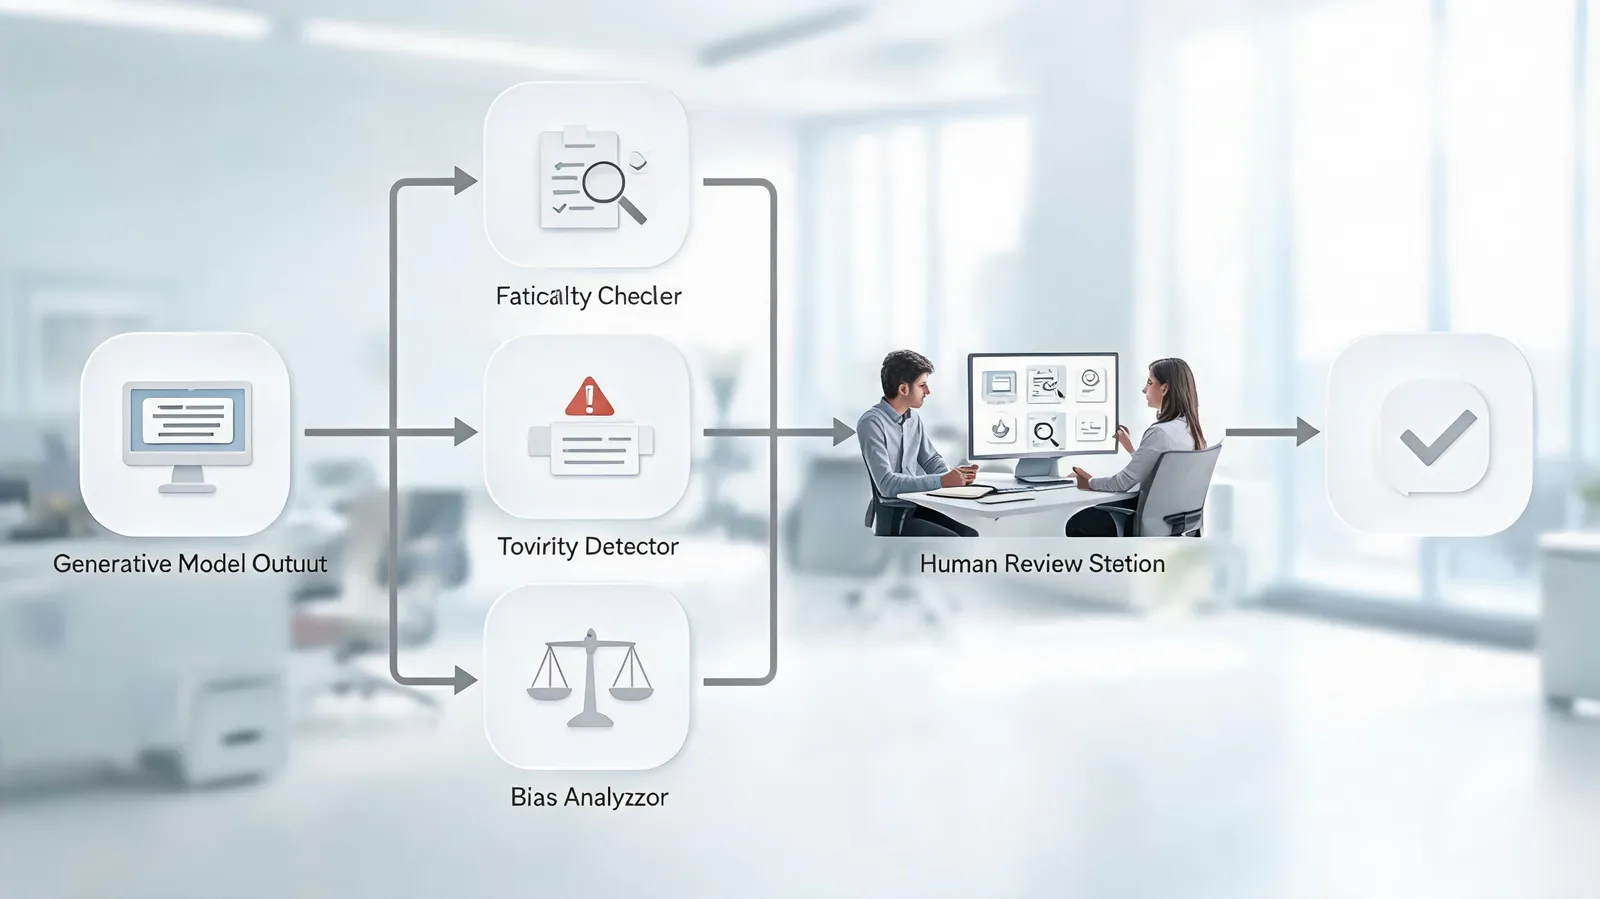
Gauging the quality and harms of generative output calls for an approach with several dimensions. Factuality work centers on whether generated text is truthful. Common instruments include the FEVER score, factual consistency metrics, and human evaluation protocols. Still, judging factuality in open-ended generation is difficult, since there is no single ground truth to compare against.
For toxicity and stereotyping, detection combines automated tooling with human-in-the-loop review. The Perspective API, for example, can flag toxic content, while techniques such as word embedding association tests quantify stereotyping. Bias audits that pair automated analysis with human review give a fuller picture of how a model behaves.
3. Reducing Harm Through Data Curation, Fine-tuning, and Guardrails
A multi-layered defense is needed to reduce bias and harms in generative models. Data curation means balancing datasets and stripping out harmful content. Re-sampling and re-weighting are among the techniques that can debias training data, and curated datasets that better represent marginalized groups are essential.
Fine-tuning and guardrails supply interventions at the model level plus filtering of outputs. Methods such as adversarial training and reinforcement learning from human feedback (RLHF) lower toxicity. Deploying guardrails — content filters and bias detectors among them — helps keep production systems in line with ethical standards.
Conclusion
Tackling bias, quality problems, and representational harms in generative models matters for fairness and for trust in AI. Understanding bias sources, applying sound evaluation methods, and layering mitigation strategies can move us toward more ethical generative AI. Sustained work is still required to standardize evaluation, encourage inclusive data practices, and build guardrails that adapt as models change.