Compliance Obligations for Domain-Specific AI in Health and Finance
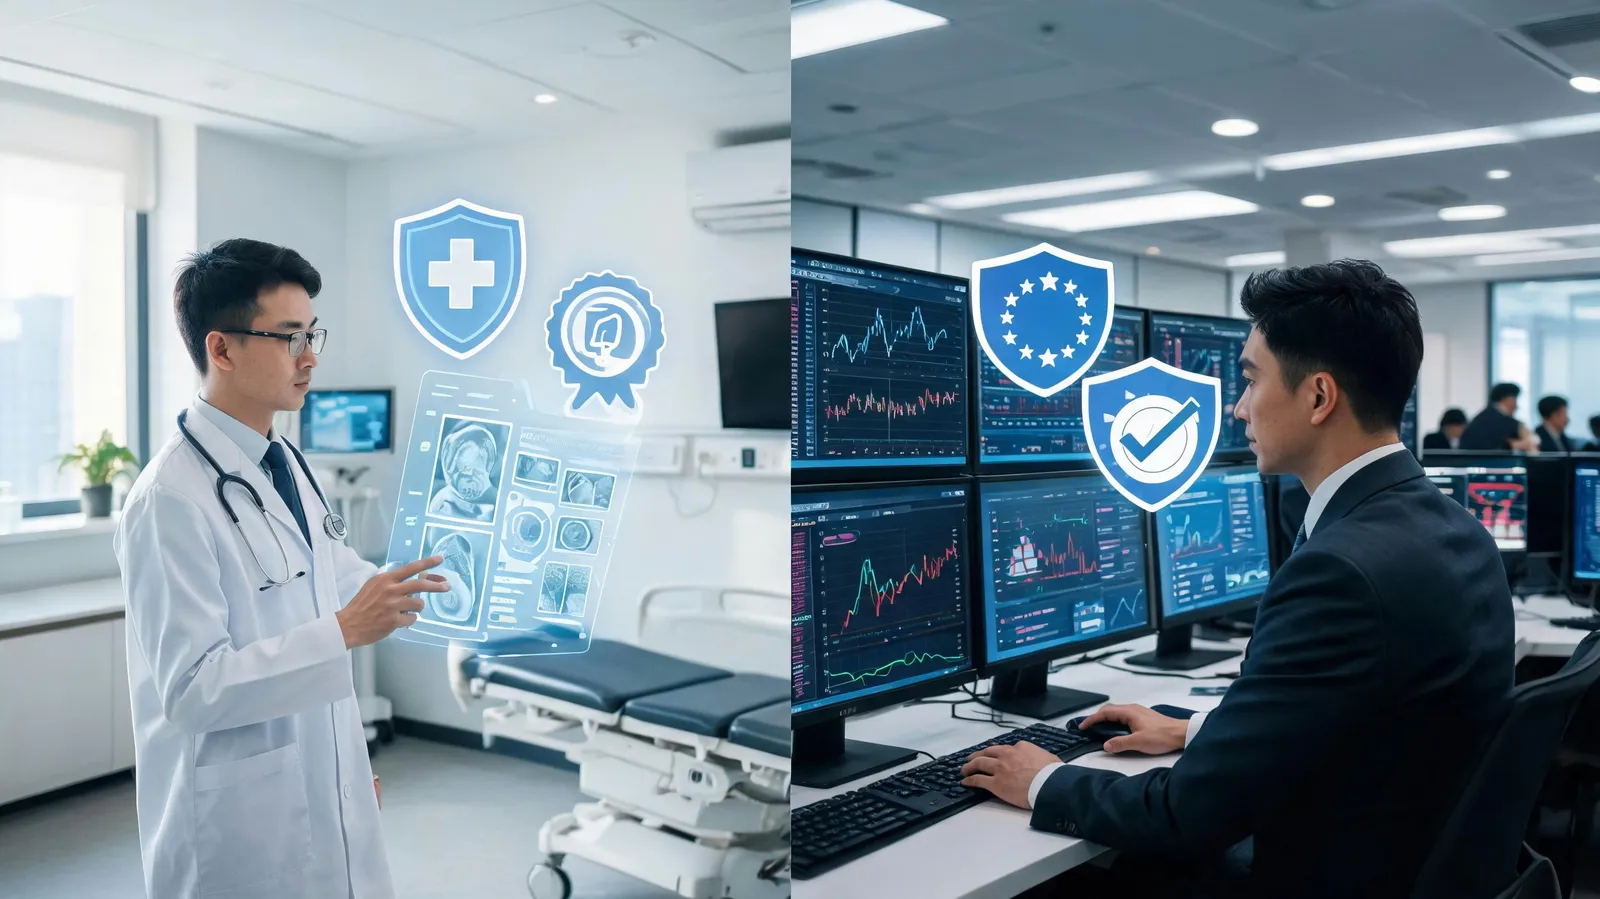
AI built for a single industry does not operate in a legal vacuum. Health and finance each carry their own rulebooks, and those rules differ by jurisdiction and by how the system is used. Meeting them is not a nice-to-have; deployment depends on it.
Health: HIPAA, GDPR, and FDA Review
In the U.S., any AI that touches protected health information (PHI) falls under the Health Insurance Portability and Accountability Act (HIPAA). Practically, that means strong encryption, tight access controls, and audit trails that record who saw what. For systems processing data belonging to EU citizens, the General Data Protection Regulation (GDPR) adds further duties, among them explicit consent and data minimization.
Medical AI devices are overseen by the U.S. Food and Drug Administration through its Software as a Medical Device (SaMD) pathway. A model that flags diabetic retinopathy in retinal images, for instance, needs FDA clearance showing it is safe and effective. The agency also stresses explainability: clinicians must be able to follow how a model reached its conclusion before they rely on it.
Getting compliance wrong carries real costs. A healthcare AI startup was penalized in 2021 for using patient data without proper consent, a case that underlines the value of disciplined data governance. Sound practice includes periodic compliance audits, bringing legal expertise in early, and building models with transparency as a design goal.
Finance: Fair Lending, AML, and Model Risk
Financial AI must respect fair lending statutes such as the Equal Credit Opportunity Act (ECOA), which bars discrimination on the basis of race, gender, and other protected traits. A credit-scoring model has to explain its outputs and show that it does not discriminate by accident. Guidance from the Consumer Financial Protection Bureau (CFPB) requires lenders to send adverse action notices explaining why an applicant was turned down—a hard requirement for opaque models.
Anti-money laundering (AML) rules oblige institutions to watch transactions for suspicious activity. Domain-specific models can sharpen that work by spotting patterns associated with laundering, but the models themselves have to be auditable. Under the Federal Reserve's SR 11-7 guidance on model risk management, banks must validate and document their models, confirming both conceptual soundness and expected performance.
Examples show what goes wrong. In 2020, a large bank was fined over an AI model that ran afoul of fair lending law, producing discriminatory lending outcomes. Institutions can reduce that risk through continuous monitoring, bias testing, and clear records of how models were developed and validated.
Thin Data and the Fine-Tuning Problem
Limited data is a core obstacle for domain-specific AI. General models can draw on vast, varied web corpora; specialized ones often depend on proprietary, siloed, or scarce data. Rare diseases in healthcare may have only a few documented cases, which makes training a reliable model difficult. Fraud detection in finance suffers from severe class imbalance, since fraudulent transactions are a tiny share of the whole.
The numbers show how widespread the problem is. A 2023 survey by AI research firm Cognilytica found that 78% of organizations name data scarcity as a leading challenge in developing vertical AI. Labeled data is especially scarce in healthcare: a study in Nature Medicine found that just 3% of medical imaging data is annotated, which constrains diagnostic AI development.
Transfer Learning, Few-Shot Learning, and Synthetic Data
Developers work around scarcity with fine-tuning strategies. Transfer learning takes a pre-trained general model (BERT or GPT, for example) and adapts it to a domain using a smaller, domain-specific dataset—a general language model fine-tuned on electronic health records to extract medical entities, say. Few-shot learning pushes further, letting a model learn from only a handful of examples per class, which suits rare disease diagnosis where cases are few.
Synthetic data is another route. Artificially generated but realistic data points can expand a limited dataset; in finance, synthetic transactions can mimic fraudulent patterns without exposing real customer information. The catch is that synthetic data needs careful validation so it does not introduce bias or unrealistic patterns.
Results exist. A pneumonia-detection model for chest X-rays, fine-tuned via transfer learning on 5,000 images, reached 95% accuracy—better than a general model trained on millions of images. A fraud detection model built with few-shot learning cut false positives by 30% while keeping detection rates high.
Each technique fits a different situation: transfer learning works best when domain data is moderately available, few-shot learning when it is extremely scarce, and synthetic data is flexible but demands rigorous validation. Combining them often produces the strongest outcome.
Measuring Specialized AI Against General Models
Comparing the two is difficult. Standard benchmarks such as GLUE and SuperGLUE were built for general language understanding and do not capture domain nuance; a general model may shine on trivia while stumbling on diagnosis tasks that require specialized knowledge.
Evidence points to domain models winning on domain tasks. A 2023 study in the Journal of the American Medical Association reported that a specialized model diagnosing rare genetic disorders reached 88% accuracy, against 62% for GPT-4. In finance, a specialized model predicting stock movements beat a general one by 15 percentage points in precision.
Building Benchmarks for a Single Domain
Accurate evaluation calls for domain-specific benchmarks with metrics that fit the field—sensitivity and specificity in healthcare, the Sharpe ratio in finance, for example. Datasets should mirror real-world distributions and include hard cases.
Evaluation should also account for regulation. A healthcare benchmark might test explainability, checking that clinicians can interpret a model's decisions; a finance benchmark might test fairness by measuring disparate impact across demographic groups.
The Medical Imaging and Data Resource Center (MIDRC) has built a benchmark for COVID-19 detection in chest X-rays, with a standardized dataset and metrics. In finance, the Financial Industry Regulatory Authority (FINRA) has proposed an AML benchmark that weighs detection rates against false positives.
Useful vertical benchmarks tend to share a few traits: domain experts help define the tasks, datasets are diverse and representative, and regulatory criteria are folded into the evaluation. Because domains shift, the benchmarks need regular revision.
Conclusion
Specialized AI could reshape entire industries, but data scarcity, regulatory compliance, and benchmarking stand in the way. Scarcity calls for creative fine-tuning—transfer learning, few-shot learning, synthetic data. Compliance demands attention to sector rules, from HIPAA in healthcare to fair lending law in finance. Measurement requires domain-specific metrics and datasets that reflect each field's particular demands.
Clearing these hurdles is what lets specialized AI deliver accurate, compliant, and trustworthy systems. Going forward, researchers, practitioners, and regulators will need to work together on standardized benchmarks and clear regulatory frameworks. Tackling these problems directly is how adoption speeds up and meaningful innovation spreads across healthcare, finance, and other fields.