Beyond Metrics: How Interpretability Tools Reshape AI Error Diagnosis
Artificial intelligence is now woven into critical areas—healthcare, finance, autonomous driving, and criminal justice—where a single failure can have serious repercussions. Conventional debugging instruments, including accuracy metrics and loss curves, offer no insight into the specific reasons behind a model's mistake, so engineers cannot easily trace the root cause. A set of explainability and interpretability methods—SHAP, LIME, attention maps, counterfactual analysis, and causal debugging—provides effective ways to diagnose and correct errors, bias, and safety problems, changing how black-box models are debugged.
1. Applying SHAP, LIME, and Attention Maps to Error Analysis
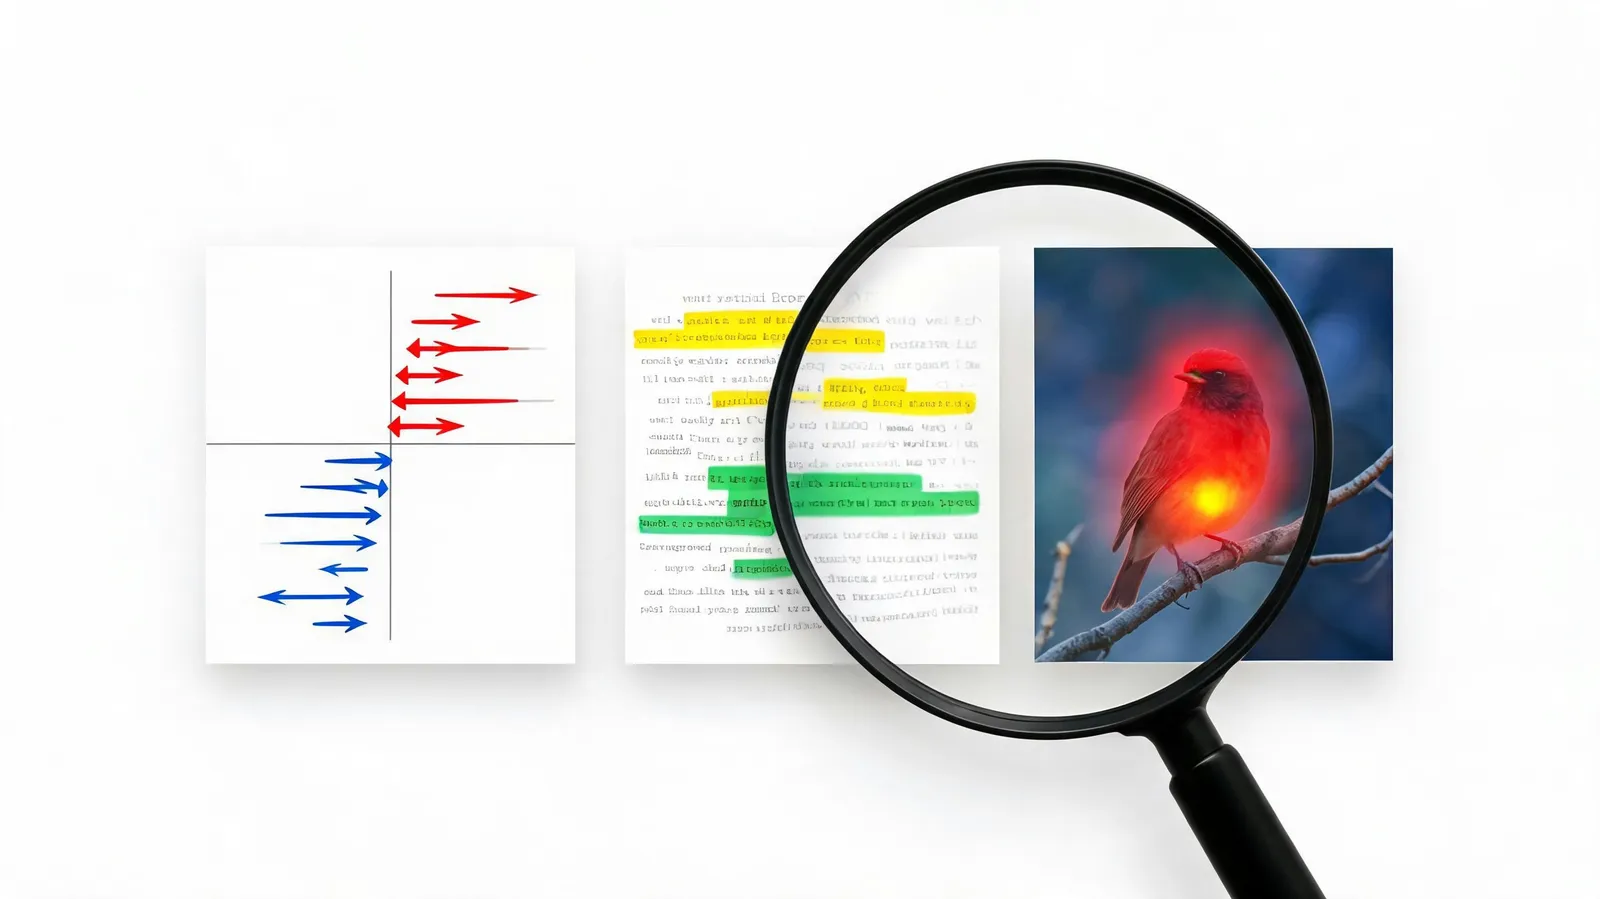
Local explanation techniques like SHAP (SHapley Additive exPlanations) and LIME (Local Interpretable Model-agnostic Explanations) produce feature-level attributions that show which inputs contribute to an incorrect prediction. In a medical diagnosis model, for instance, SHAP values can bring to light spurious correlations—such as the model depending on artifacts specific to a hospital rather than actual symptoms. Likewise, LIME can identify text features that cause misclassification in sentiment analysis, allowing engineers to determine precisely which words or phrases misled the model.
Attention maps in deep learning models, especially transformers, display where the model directs its focus. In natural language processing, such maps can reveal attention to irrelevant tokens that leads to wrong answers; in computer vision, they can expose overfitting to background artifacts. By making misdirected attention visible, these maps support targeted remedies, such as data augmentation or architectural changes.
2. Counterfactual and Causal Debugging of Model Decisions
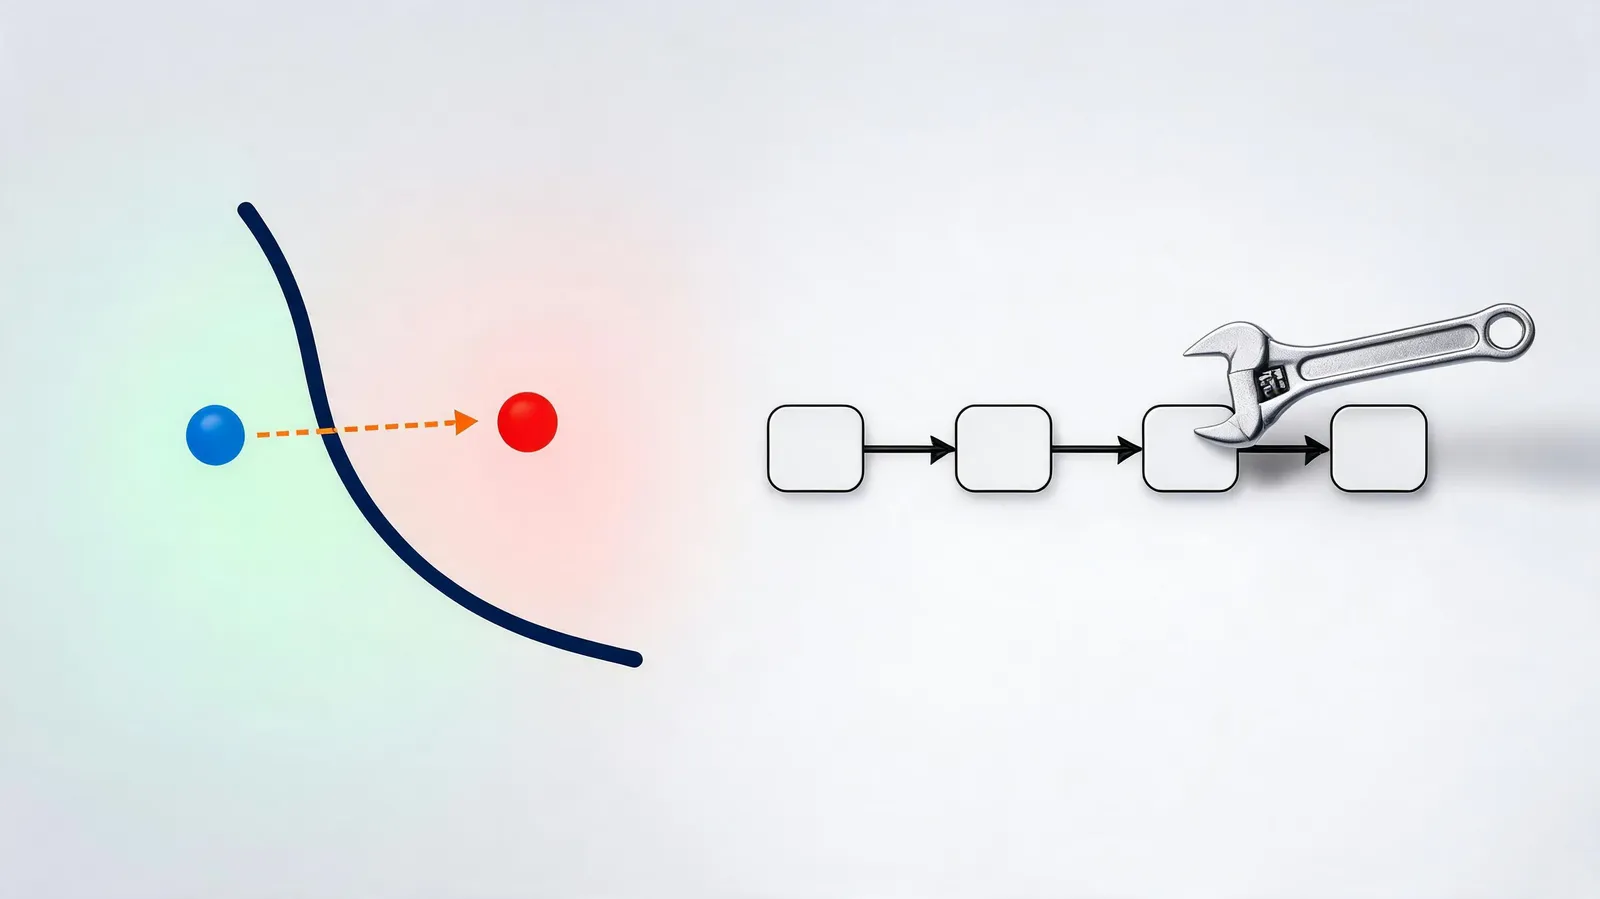
Counterfactual explanations identify minimal changes to the input that would change the prediction, thereby exposing decision boundaries. In a loan rejection case, for example, counterfactuals can indicate what income level would have led to approval, revealing fragile decision boundaries that may signal overfitting or unfairness. This method is particularly valuable for debugging models in which small, realistic changes should not reverse the outcome.
Causal debugging moves past correlations to uncover genuine cause-and-effect relationships, helping to correct models that depend on confounders. A causal graph analysis, for instance, might show that a model uses race as a proxy for income, producing discriminatory results. By eliminating non-causal features, engineers can enhance robustness and fairness. Case studies demonstrate that causal debugging can substantially improve model reliability in areas such as credit scoring and healthcare.
3. Debugging Bias and Fairness Failures
Explanation techniques can expose disparate impact by highlighting features that correlate with protected attributes. SHAP values, for example, might reveal gender as a top feature in a hiring model, while LIME can audit racial bias in recidivism prediction. These insights allow engineers to detect bias that would otherwise stay hidden behind aggregate accuracy metrics.
Fairness debugging is an iterative process of model adjustment guided by interpretability findings. Tools such as AI Fairness 360 and What-If Tool incorporate explainability to help reduce bias in credit scoring by removing proxy features identified through explanations. This cycle—detect, explain, mitigate, and validate—is essential for building fair and trustworthy AI systems.
4. Limits of Explainability in Safety-Critical Systems
Explanation methods can be unreliable or misleading, particularly for complex models like deep neural networks. Adversarial attacks on explanations can lead to misinterpretation, and research shows disagreement among explanation methods, making it difficult to rely on any single explanation. In safety-critical domains such as healthcare and autonomous driving, this unreliability creates significant risks.
Safety-critical domains demand rigorous validation and may require hybrid approaches. FDA guidelines on AI/ML in medical devices, for example, stress interpretability but also call for formal verification combined with explainability. Similarly, autonomous driving systems may need redundant, interpretable subsystems to ensure safety. The tension between explainability and safety requirements calls for a cautious, multi-faceted approach.
Conclusion
Explainability and interpretability techniques—SHAP, LIME, attention maps, counterfactuals, causal methods, and bias debugging tools—together strengthen model debugging by providing actionable insights into why models fail. They serve not only transparency but also as practical debugging instruments for building reliable, fair, and safe AI. Future directions include integrating explainability with automated debugging pipelines and developing more robust, causally-aware explanation methods. As AI systems grow more complex, explainability debugging will become indispensable for engineers and researchers alike.