A wide gap still separates AI experiments from systems that run at scale. Even as the underlying technology advances quickly, many organizations pour money into research and development while only some manage to fold those tools into day-to-day operations. The analysis below draws on documented deployments involving startups and Fortune 500 companies, spanning finance, healthcare, and the public sector, to identify the patterns, missteps, and practices that mark the difference between rollouts that stick and efforts that quietly wind down.
Enterprise Rollouts: What Worked, What Failed, and Why
Big organizations hold the budgets, data, and people needed for ambitious AI programs, but their paths to adoption are rarely smooth. Looking at deployments that succeeded alongside those that did not yields practical guidance for organizations starting their own transformations.
What Sets Successful Enterprise Deployments Apart
Several traits recur among enterprise programs that reached production. Executive backing coupled with a clear strategic link is essential. Initiatives tied directly to business goals — cutting operating costs by 20%, for instance, or lifting customer retention — tend to get the funding and attention needed to push through obstacles. Data infrastructure maturity is another major factor. Organizations that built data lakes, governance frameworks, and real-time pipelines ahead of their AI efforts consistently outperform peers that try to build on fragmented, siloed data systems.
One illustration: a Fortune 500 financial services firm extended AI across risk assessment, fraud detection, and customer service. It created a central AI platform team that supplied reusable tools, pre-approved models, and compliance guardrails; as a result, model deployment time fell from nine months to six weeks. The approach was estimated to save $120 million annually through more accurate fraud detection and less manual review work.
Typical Failure Modes
On the flip side, enterprise failures tend to come from predictable places. Data silos remain the biggest culprit: when data science teams cannot reach critical data held by other business units, model development stalls. When executive support fades after the initial pilot, projects get stuck in "pilot purgatory" and never secure production funding. And when change management needs are underestimated, user adoption drops even where the technical build succeeds.
Industry surveys suggest roughly 70–80% of enterprise AI projects never scale past the pilot stage. One large healthcare system spent $15 million on an AI diagnostic tool and abandoned it after 18 months, because clinicians found the interface unwieldy and did not trust the model's recommendations. The technology functioned; the human and process elements did not.
How Startup and Enterprise AI Workflows Differ
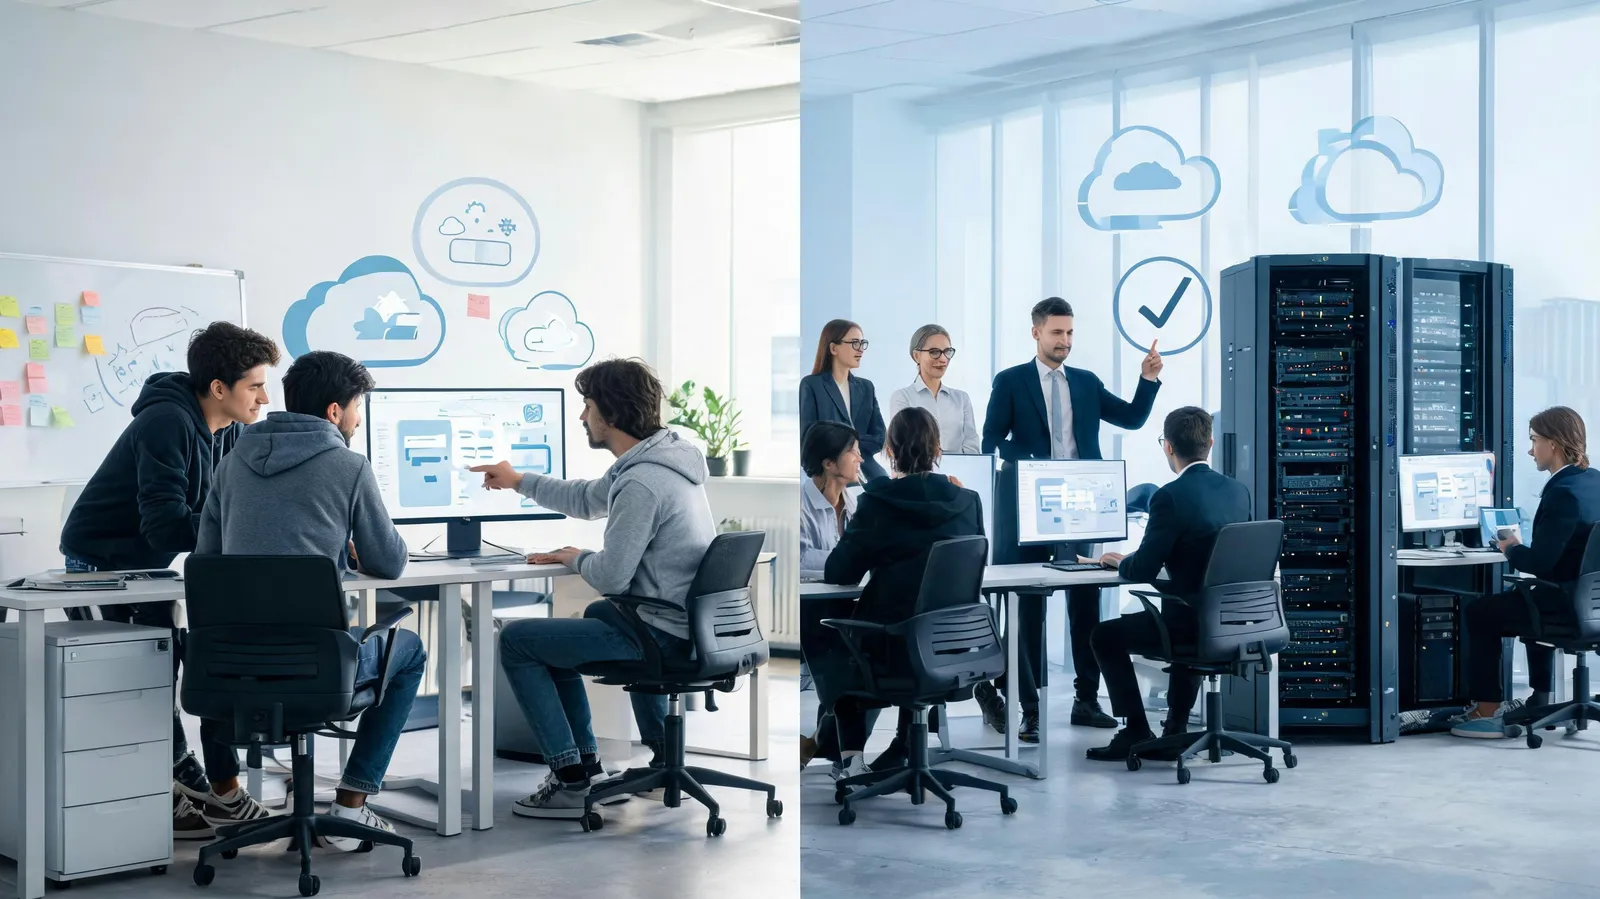
Startup and enterprise AI development workflows contrast sharply, a reflection of different organizational structures, risk appetites, and resource limits. Mapping these differences helps both kinds of organizations choose practices suited to their circumstances.
Speed and Experimentation in Startups
Startups prioritize speed and flexibility. Their workflows usually rely on small, cross-functional teams in which data scientists, engineers, and product managers work side by side. Cloud-native tooling and managed services (for example AWS SageMaker, Google Vertex AI, or Azure ML) allow rapid experimentation without heavy infrastructure spending. MLOps practices — continuous integration, continuous delivery, and monitoring for machine learning — are adopted early to automate retraining and deployment.
One fintech startup shows the upside: automated MLOps pipelines let the team iterate on its credit scoring model weekly, folding in new data and feedback. Improvement cycles that once took months shrank to days, and the startup attributed a 35% gain in loan approval accuracy within six months directly to this pace.
Governance and Scale in Enterprises
Enterprises must weigh innovation against governance, compliance, and scale. Their workflows tend to involve larger teams with specialized roles — data engineers, ML engineers, data scientists, compliance officers, and domain experts. Stage-gate approvals confirm that models satisfy regulatory and ethical standards before release. Infrastructure commonly spans hybrid cloud and on-premises systems to meet data residency and security needs.
A manufacturing company's AI platform illustrates the trade-off: its workflow included automated model documentation, bias testing, and human-in-the-loop review for high-stakes decisions. Deployment timelines grew by two to three weeks, but the company avoided costly regulatory penalties and preserved customer trust.
Adoption in Finance, Healthcare, and the Public Sector
Each industry confronts distinct constraints and openings when adopting AI. Sector-level examples show how regulation, data sensitivity, and operational priorities shape implementation choices.
Finance: Risk, Fraud, and Customer Service
Financial services adopted AI early and aggressively, pushed by the need for real-time risk assessment, fraud detection, and personalized service. A major U.S. bank deployed an AI fraud detection system that examines transaction patterns in milliseconds, cutting false positives by 40% and saving an estimated $50 million a year in prevented fraud losses.
Regulatory hurdles are substantial, however. Financial institutions must comply with rules such as the Fair Credit Reporting Act, the Equal Credit Opportunity Act, and various anti-money-laundering requirements. Implementations that work include explainable AI components able to justify decisions to regulators and customers. The bank's system used SHAP (SHapley Additive exPlanations) values to make model decisions transparent, satisfying internal audit and external regulatory requirements alike.
Healthcare: Diagnostics and Patient Care
Healthcare examples show both large potential and distinctive challenges. AI in medical imaging has delivered notable results: a large hospital network deployed a system to detect early-stage lung cancer from CT scans, reaching 94% sensitivity versus 87% for human radiologists working alone. Earlier interventions improved patient outcomes, and radiologist workload dropped by 30%.
Still, healthcare AI faces strict rules (HIPAA, FDA clearance for clinical decision support tools) and ethical questions around patient consent and algorithmic bias. The hospital network responded with extensive bias testing across demographic groups and continuous monitoring for model drift. Its experience shows that success in healthcare AI depends on close collaboration among technologists, clinicians, and compliance teams.
Public Sector: Citizen Services and Infrastructure
Government agencies increasingly use AI to improve citizen services and optimize infrastructure. A state department of transportation deployed an AI traffic optimization system that cut average commute times by 18% and lowered carbon emissions by 12% through adaptive signal timing. The system draws on real-time data from thousands of sensors and cameras to adjust traffic flows dynamically.
Public-sector examples also highlight ethical and transparency concerns. The transportation agency held public hearings and published algorithmic impact assessments to build trust. It also set up an oversight committee that included community representatives to review system performance and address concerns. This participatory approach was slower than private-sector deployment, but it proved essential to keeping public support.
Comparing AI Workflows Across Organizations
Benchmarking metrics, together with patterns and anti-patterns drawn from cross-industry examples, can help organizations assess and improve their own AI development workflows.
Metrics That Matter for Workflow Efficiency
Useful benchmarking relies on quantifiable measures that capture both technical and organizational performance. Key metrics include:
- Model deployment time: Elapsed time from model completion to production release. Leading organizations manage days; laggards take months.
- Data pipeline latency: Time to move data from source to the model training environment. Lower latency supports faster iteration.
- Team velocity: Models deployed per quarter per data science team. High-performing teams ship 5–10 models quarterly.
- Model performance drift: The rate at which model accuracy degrades over time, signaling retraining needs.
- Incident response time: Time to detect and resolve model failures in production.
Industry surveys suggest organizations with mature MLOps practices deploy models 8–10 times more often than those without, with 50% lower failure rates.
Patterns Worth Copying and Traps to Avoid
Across the examples reviewed, several patterns separate implementations that succeed:
- Pattern: Centralized platform, decentralized execution. Successful enterprises provide shared AI infrastructure and governance while letting business units build domain-specific models.
- Pattern: Continuous monitoring and retraining. Leading organizations treat models as living assets that need ongoing maintenance, not one-off projects.
- Anti-pattern: Siloed data science teams. Isolated teams without production data access or engineering support consistently underdeliver.
- Anti-pattern: Uniform governance. Applying identical approval processes to low-risk and high-risk models creates needless bottlenecks and encourages shadow AI.
One retail company offers a cautionary case: it set up a separate AI innovation lab disconnected from business units. The lab produced impressive prototypes, but none reached production because it lacked integration with existing systems and processes. The company eventually disbanded the lab and placed data scientists directly in product teams, which led to successful deployments within six months.
Conclusion
Moving from AI experimentation to production-scale adoption is neither simple nor uniform. The examples above, drawn from enterprises, startups, and several sectors, suggest that success rests less on cutting-edge algorithms than on organizational factors: executive alignment, data infrastructure, change management, and fit-for-purpose governance.
Enterprises can borrow from startups' speed and experimentation culture, while startups can learn from enterprises' discipline around governance and scale. Sector-specific factors — regulatory requirements in finance, ethical concerns in healthcare, transparency demands in the public sector — need to shape implementation strategy from the start rather than be handled afterward.
Benchmarking against key metrics and avoiding common anti-patterns offers a path to improvement. As AI technologies keep evolving rapidly, the organizations that thrive will be those that build adaptable workflows able to absorb new capabilities while preserving trust and accountability. The lesson running through these deployments is consistent: technology is necessary but not sufficient; people, processes, and governance determine success.